01
Software development
We design and build websites, apps, and business systems around your product goals, connecting planning, development, deployment, and operations.
WEB / APPS / BUSINESS SYSTEMSTurn ideas into products, and products into evidence for the next experiment.
In the AI era, an advantage comes from how quickly you can build more hypotheses at a lower cost, bring them to market, and learn from the response.
From uncertainty to a clear planFrom the business question to a working product and its day-to-day operation.
We design and build websites, apps, and business systems around your product goals, connecting planning, development, deployment, and operations.
WEB / APPS / BUSINESS SYSTEMS
We build cloud infrastructure on NCP, AWS, and Oracle Cloud, and configure GPU-powered LLM inference—from model serving to scaling—around your latency, throughput, and cost requirements.
CLOUD / GPU / LLM INFERENCE
We clarify your situation and requirements, then shape product direction, information architecture, technical scope, and the sequence of work together.
DIRECTION / STRUCTURE / EXECUTION
Software and media,
connected through delivery.
Refine product structure and user flows, and build the code and deployment environment together.
Translate the message behind a brand or product into content and digital experiences.
We support architecture, deployment, migration, and operations on NCP (NAVER Cloud Platform), AWS, and Oracle Cloud, connecting application services with the infrastructure they need.
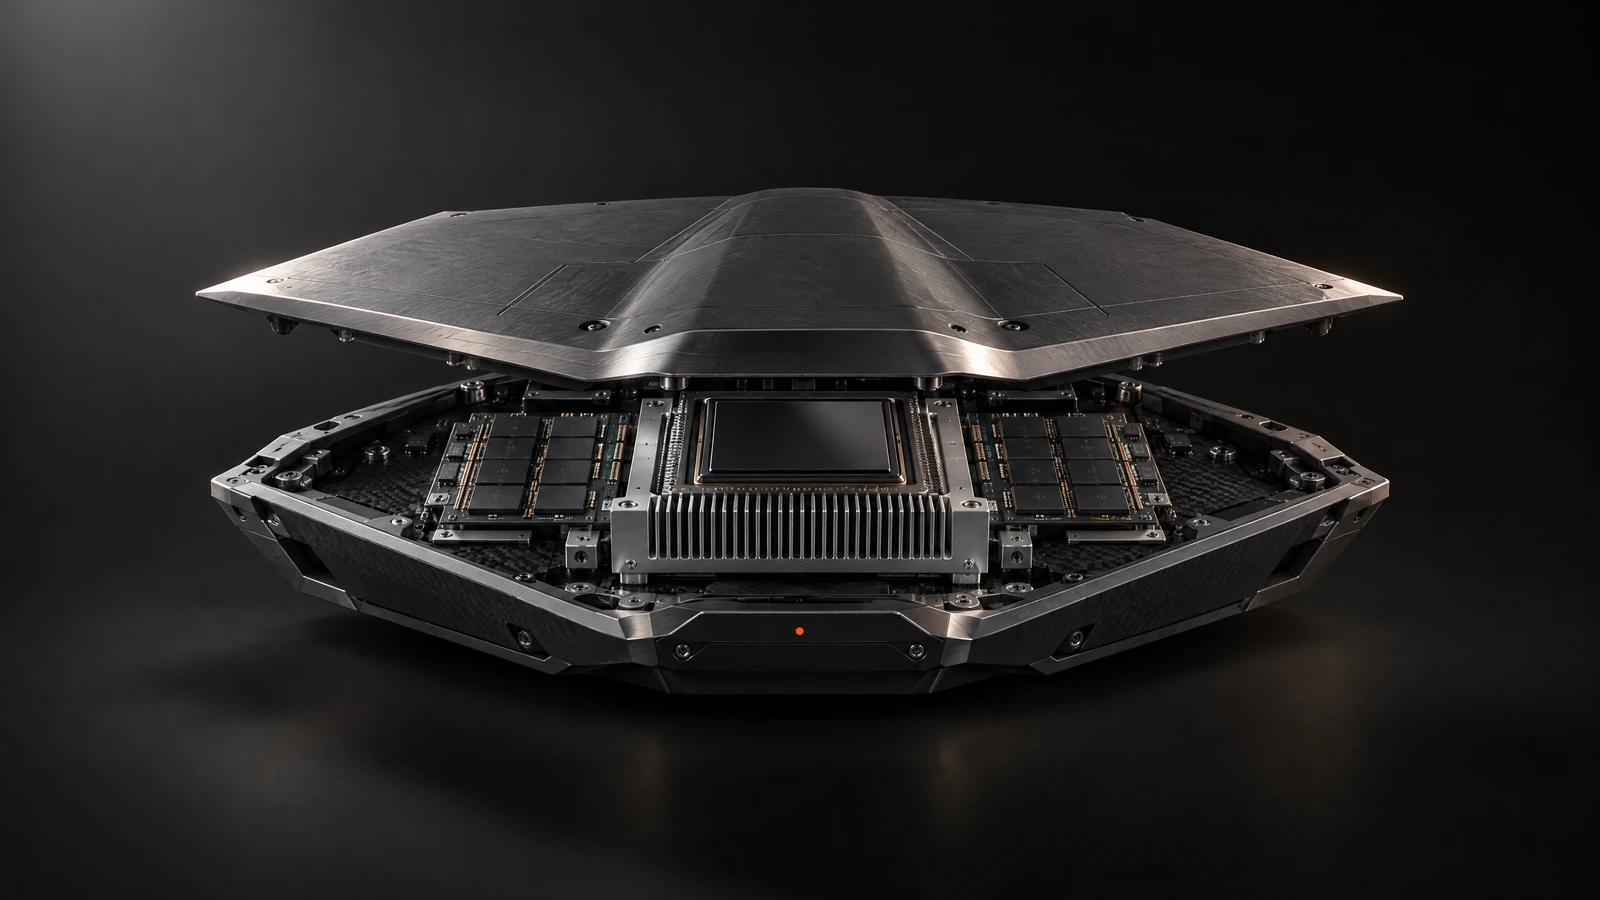
We size GPU memory and compute for your models, set up LLM serving endpoints, and tune batching and scaling for response time, throughput, and cost—on cloud GPUs or dedicated servers.
Together, we choose a combination that fits the purpose and scale of your project.
Clarify the goals and requirements together,
then connect delivery to operation.
We review goals, users, existing systems, and operating conditions together.
We turn the necessary features, content, and technical constraints into a clear scope.
We design priorities, information architecture, user flows, and the technical setup.
We deliver software, infrastructure, and media through a single execution plan.
We check the deployment and prepare the ground for the next improvements.
/ˈparəˌkɒzəm/ noun
A richly imagined world.
Ours just happens to be built in software.
From what to build to how to operate it, we work through the questions that matter together.
Software, cloud infrastructure, GPU-powered LLM inference, planning, consulting, and media—connected around the needs of your project.
A look inside our workshopWe support software development, cloud infrastructure, GPU-powered LLM inference, project planning and consulting, and media production. Together, we decide which capabilities your project needs.
No. A problem you care about is a good place to begin. We can work through the opportunity, define a focused first version, and decide what is worth building.
We start with goals, users, existing systems, and operating conditions. Then we define requirements and structure before moving into production, launch, and operations.
Yes. We support NCP, AWS, and Oracle Cloud setup, migration, and operations, as well as GPU-based LLM serving. We review model size, expected traffic, latency targets, and data requirements to choose between cloud GPUs and dedicated infrastructure.


